Log inSign up
Log inSign up
André Silva
1,081 posts
André Silva profile banner
@andre15silva_

André Silva

@andre15silva_
PhD at KTH 🧑‍🍳 ML on Code
Stockholm, Sweden
andre15silva.github.io
Joined November 2015
819 Following
152 Followers
RepliesRepliesRepostsRepostsMediaMedia

Log in or sign up for X

See what’s happening and join the conversation

Continue with phone
or
Log in with username or email
Terms·Privacy·Cookies·Accessibility·US TIDA·Ads Info·© 2026 X Corp.
  • @andre15silva_
    André Silva
    @andre15silva_
    Oct 5
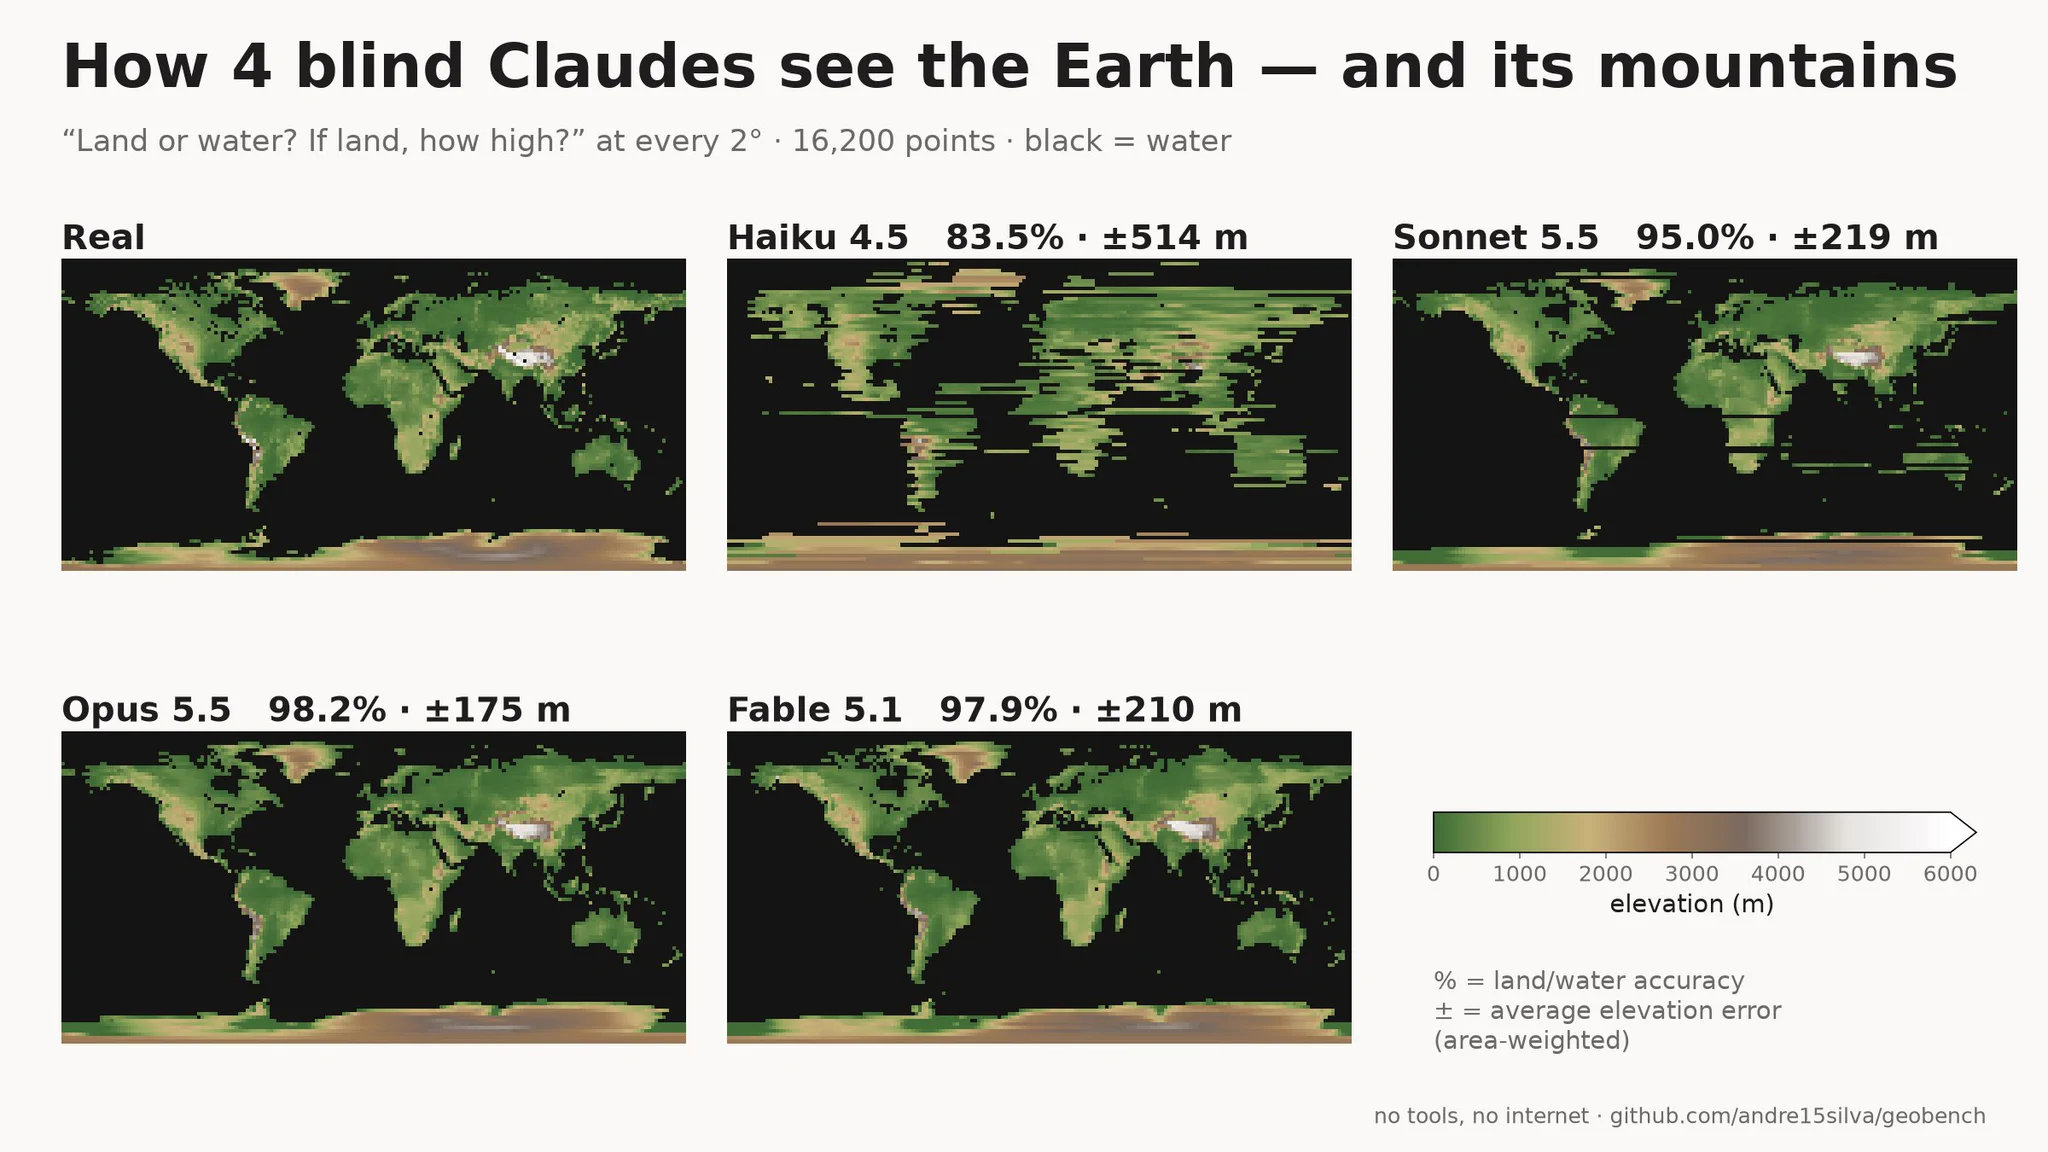
    it also knows elevation!
    @celestepoasts
    Celeste
    @celestepoasts
    Sep 24
    Replying to @celestepoasts
    results for all claudes
    1
  • @andre15silva_
    André Silva
    @andre15silva_
    Jul 14
    When a coding agent works, it spends dozens of steps reasoning, editing code, and running commands. Yet little is known about what the underlying model internally encodes about the programs it works on. We looked inside the model's hidden states to see what they actually encode.
    1
  • @andre15silva_
    André Silva
    @andre15silva_
    Apr 21
    ✈️ Travelling to ICLR 🇧🇷 this week! Will be presenting our work "On Randomness in Agentic Evals" at the Agents in the Wild workshop. If you're also attending ICLR would be more than happy to talk about anything machine learning on code😀
    1
  • @andre15silva_
    André Silva
    @andre15silva_
    Mar 22
    lol, what a joke. add this to our findings about randomness in agentic evals (arxiv.org/pdf/2602.07150) and you have the perfect storm for unsound claims. if you're doing research on top of llms (esp. via api), be extra careful
    @timotheechauvin
    Timothée Chauvin
    @timotheechauvin
    Mar 22
    Replying to @timotheechauvin
    We also found instances of undisclosed changes with Border Input tracking. Actually, one of them was disclosed: did you know that if you had something running on "Mistral-7B-Instruct-v0.3" from @togethercompute , they silently (though with a public announcement) redirected it to
  • @andre15silva_
    André Silva
    @andre15silva_
    Feb 10
    🧵Have you been skeptical of SWE-Bench scores?🔎 You have reason to be! In our new paper "On Randomness in Agentic Evals", we analyze 60k agent trajectories on SWE-Bench-Verified and found that single-run scores from the same agent can vary by up to 6%. Here's what we found...
    1