Log inSign up
Log inSign up
David Hall
1,983 posts
@dlwh

David Hall

@dlwh
Member of Technical Staff @ Open Athena. Creator of Levanter and Marin. Previously Research Engineering @StanfordCRFM, co-founder at Semantic Machines ⟶ MSFT.
Berkeley, CA
dlwh.org
Joined September 2007
1,322 Following
3,924 Followers
RepliesRepliesRepostsRepostsMediaMedia

Log in or sign up for X

See what’s happening and join the conversation

Continue with phone
or
Log in with username or email
Terms·Privacy·Cookies·Accessibility·US TIDA·Ads Info·© 2026 X Corp.
  • @dlwh
    David Hall
    @dlwh
    14h
    Ben’s out here spreading the good word of ultrafinitism. (But seriously, the cost model here is pretty broken.)
    @beenwrekt
    Ben Recht
    @beenwrekt
    17h
    OpenAI’s faster Fourier transform is less a mathematical breakthrough and more a malicious exploit of mathematical traditions. argmin.net/p/faster-fouri…
    2
  • @dlwh
    David Hall
    @dlwh
    Oct 10
    We’re Marin, the details are pretty much always available! github.com/marin-communit… This time we’re deploying Triton router top-k and short conv, leaner ragged a2a transport, fused expert backward, and XLA scheduling fixes
    @Kangwook_Lee
    Kangwook Lee
    @Kangwook_Lee
    Oct 9
    Replying to @dlwh and @mcmcescher
    wow, that looks amazing! are more more details available?
    2
  • @dlwh
    David Hall
    @dlwh
    Oct 9
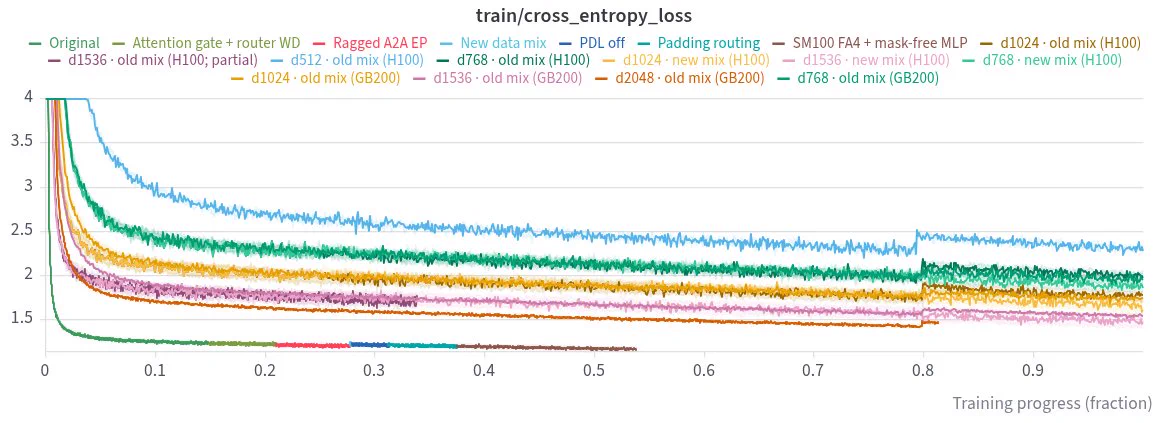
    More perf tweaks landed thanks to @mcmcescher! We're now up to ~40% more tokens-per-second than when we launched.
    graph showing MFU jumping from ~26 to ~29.4
    @percyliang
    Percy Liang
    Together AI
    @percyliang
    Oct 6
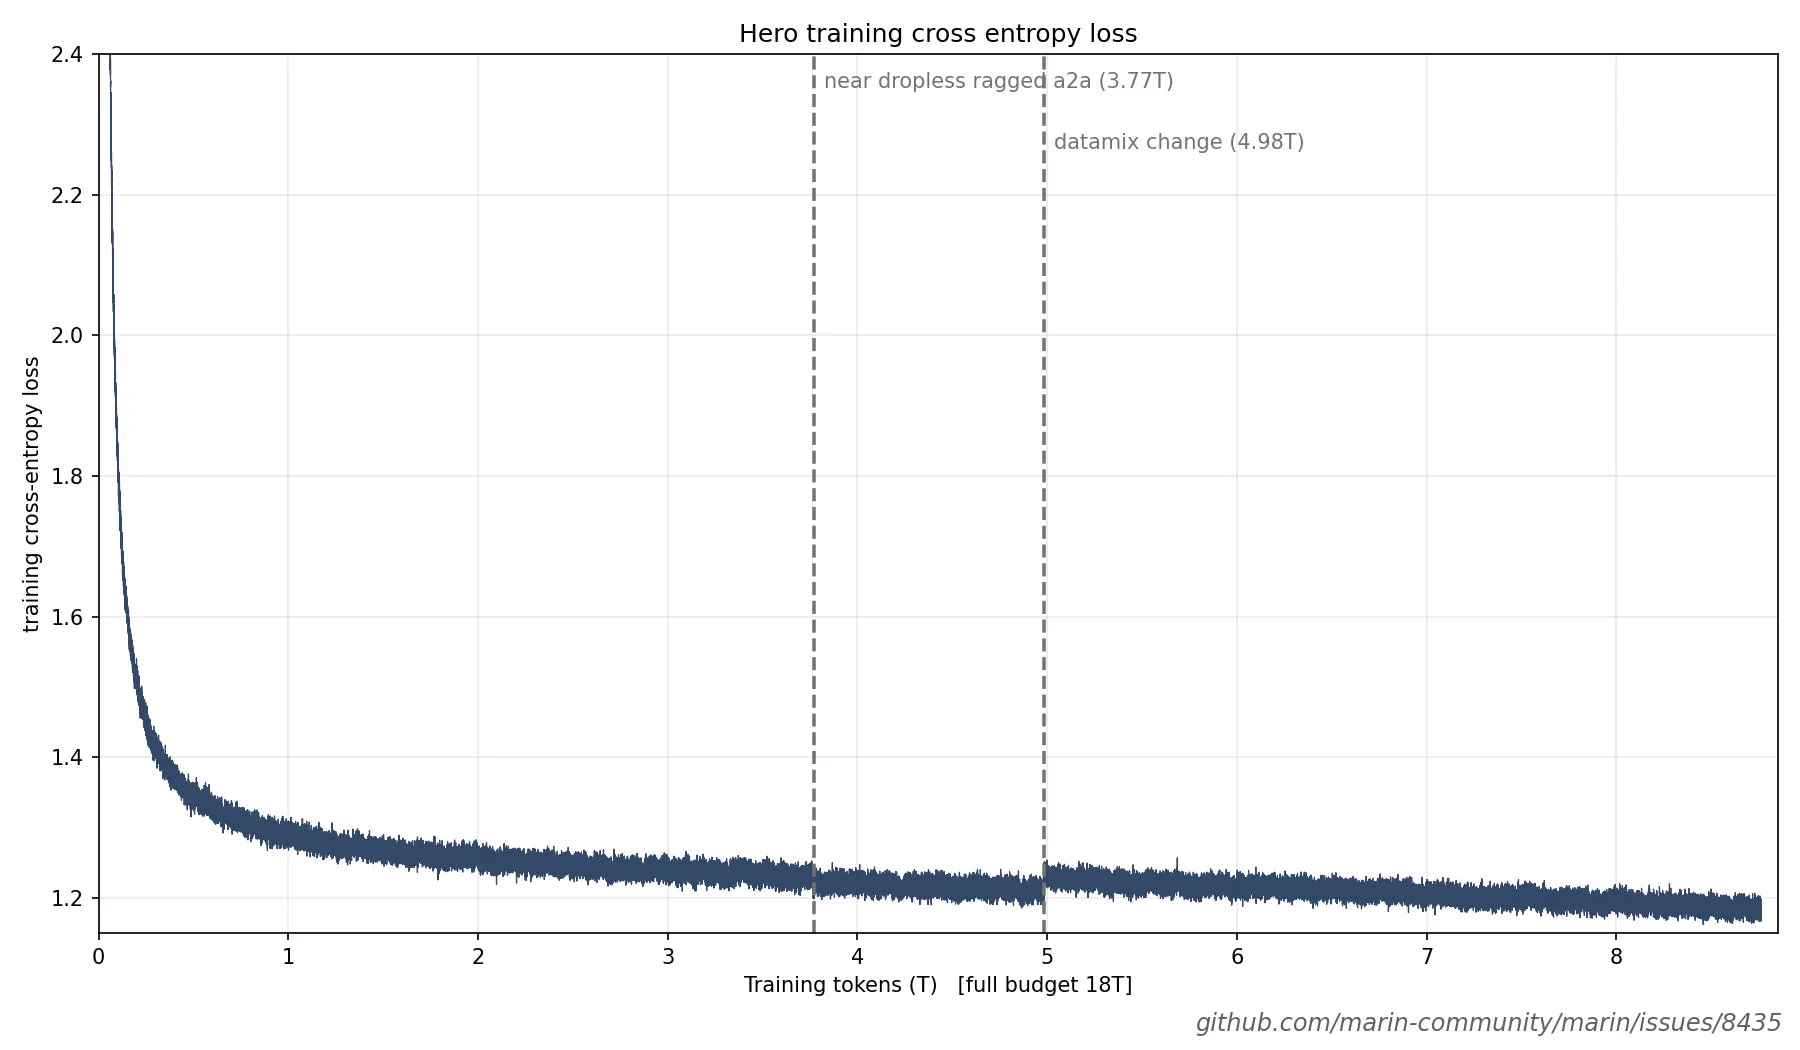
    🚢Marin 535B-A23B training has crossed the halfway mark! Some observations and learnings so far:
    1
  • @dlwh
    David Hall
    @dlwh
    Oct 2
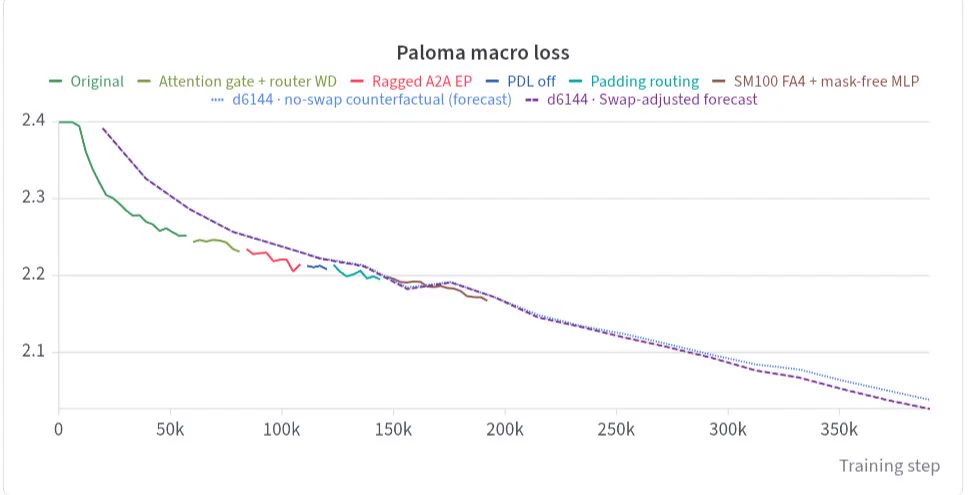
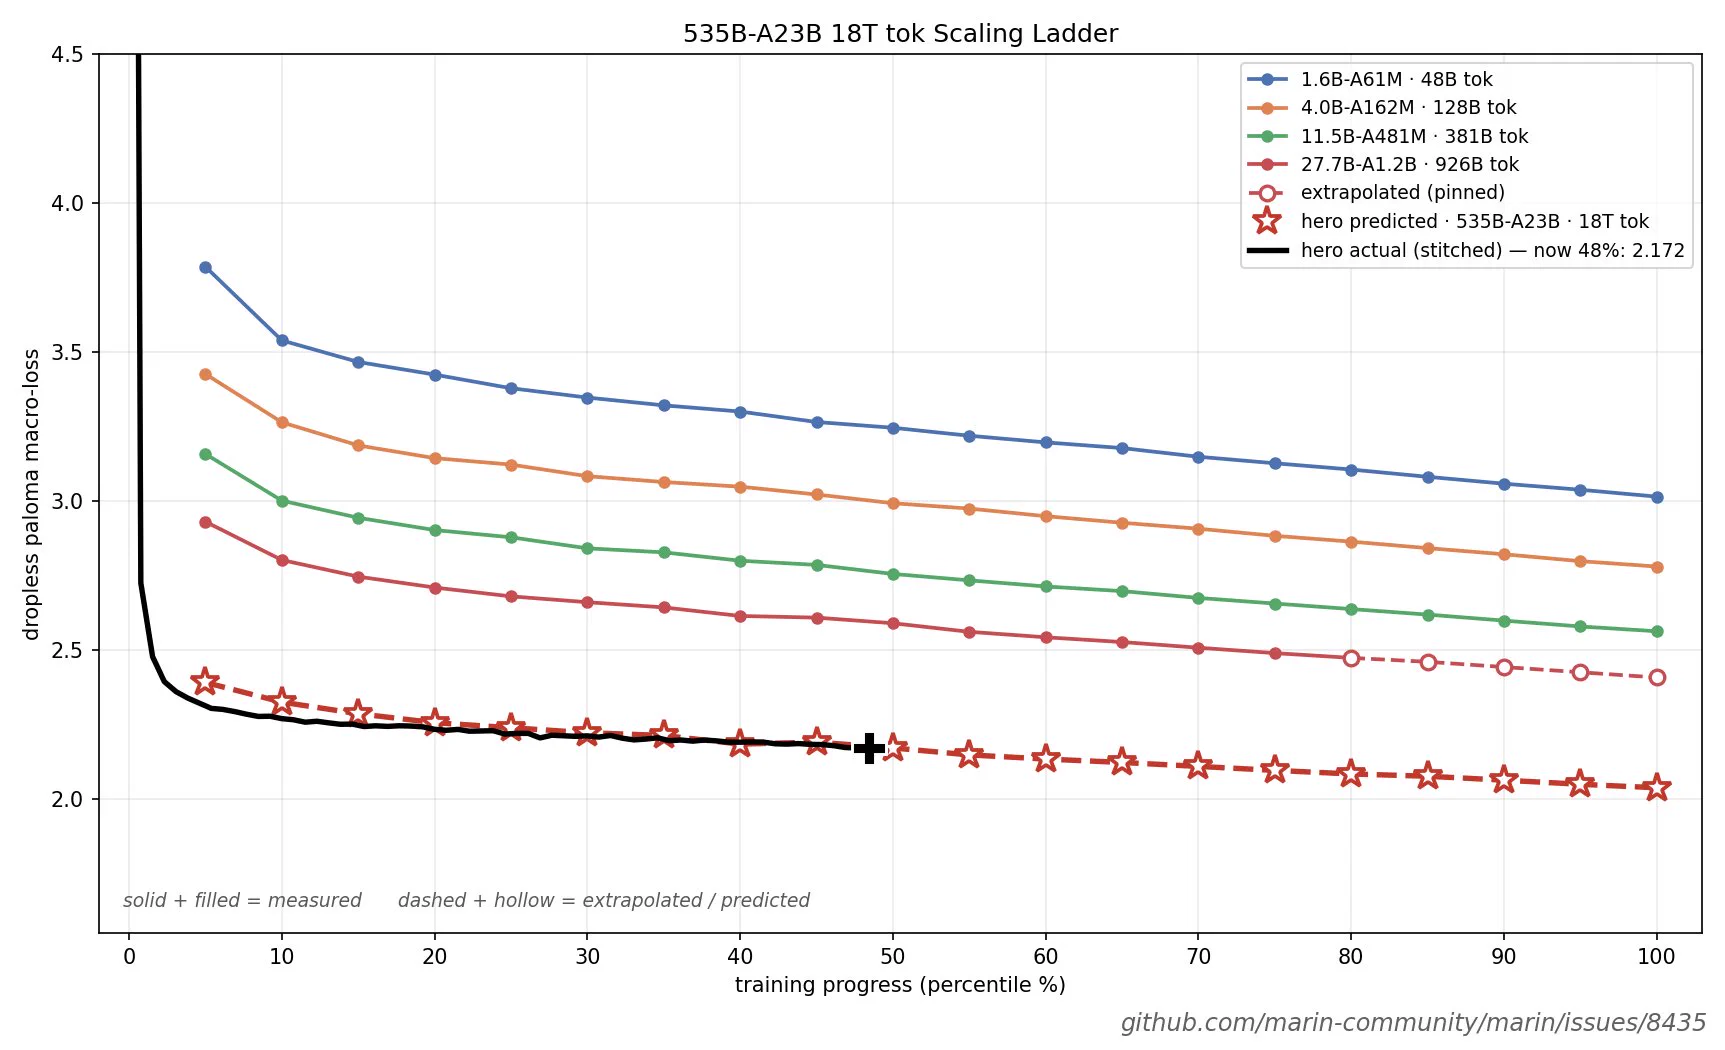
    Gotta say the imminent-looking crossing in Larry's plot is making me nervous but my friend "zoom in" is still here to help.
    zoomed in plot showing run still slightly beating forecasts
    @classiclarryd
    Larry Dial
    @classiclarryd
    Oct 1
    43 days ago Marin kicked off the largest live-streamed pretraining run in history: a 535B MoE trained on 18T tokens. A scaling ladder was used to forecast eval loss along the entire trajectory, and the forecast was publicly pre-registered. Its halfway along, and despite being a
    3
  • @dlwh
    David Hall
    @dlwh
    Oct 2
    This is the first in a series on how we got our 535B MoE hero run to ~27% MFU on 11 NVL72 racks. @ravwojdyla tackles expert parallelism: what we tried, what didn't work, the (somewhat) ugly solution we launched with, and the better solution we swapped in mid-run.
    @ravwojdyla
    Rafal Wojdyla
    @ravwojdyla
    Oct 1
    Marin’s 535B-parameter hero run was originally planned as a 360B model. In openathena.ai/blog/expert-pa… we explain how expert parallelism made room for a roughly 50% larger model, with approximately 23B active parameters per token - and the tradeoffs involved.