Log inSign up
Log inSign up
Dr G
19.1K posts
Dr G profile banner
@drguthals

Dr G

@drguthals
I'm Sarah, founding devrel engineer @tensorlake
Joined April 2009
2,572 Following
3,066 Followers
RepliesRepliesRepostsRepostsMediaMedia

Log in or sign up for X

See what’s happening and join the conversation

Continue with phone
or
Log in with username or email
Terms·Privacy·Cookies·Accessibility·US TIDA·Ads Info·© 2026 X Corp.
  • Pinned
    @drguthals
    Dr G
    @drguthals
    May 15, 2025
    I haven't posted yet about my new position because, no shade, I felt like the "I have a new role" just didn't do it justice. There are a lot of reasons I decided to join @tensorlake Here's a 🧵, but a huge part is this announcement today 👇 (1/4)
    @tensorlake
    Tensorlake
    @tensorlake
    May 15, 2025
    Announcing Tensorlake Cloud Up-leveling Document Ingestion and Workflows for building agentic applications and complex business workflows.
    00:00
    4
  • @drguthals
    Dr G
    @drguthals
    Nov 24, 2025
    Quickly process SEC filings so that you can see what AI risks NYSE companies are considering
    @motherduck
    MotherDuck
    @motherduck
    Nov 21, 2025
    Query unstructured documents with SQL?? We built a tutorial (complete with Colab notebook!) showing how Tensorlake and MotherDuck turn unstructured documents into analytics-ready datasets: 📄 Classify relevant pages in 100+ page SEC filings 🔍 Extract structured AI risk data
  • @drguthals
    Dr G
    @drguthals
    Nov 5, 2025
    We're the best in class document parsing API. You get all this 👇 out of the box, and with accuracy numbers to back it up, you can reliably parse complex documents and extract accurate date with ease. (link to our benchmarks in the comments)
    @hasantoxr
    Hasan Toor
    @hasantoxr
    Nov 5, 2025
    Turn PDF files into clean, LLM-ready data. Tensorlake's new API organized our PDF files and significantly enhanced performance. It's the first system that effectively converts disorganized PDF files into structured data. Here's how it works in 3 steps:
    GIF
    1
  • @drguthals
    Dr G
    @drguthals
    Nov 5, 2025
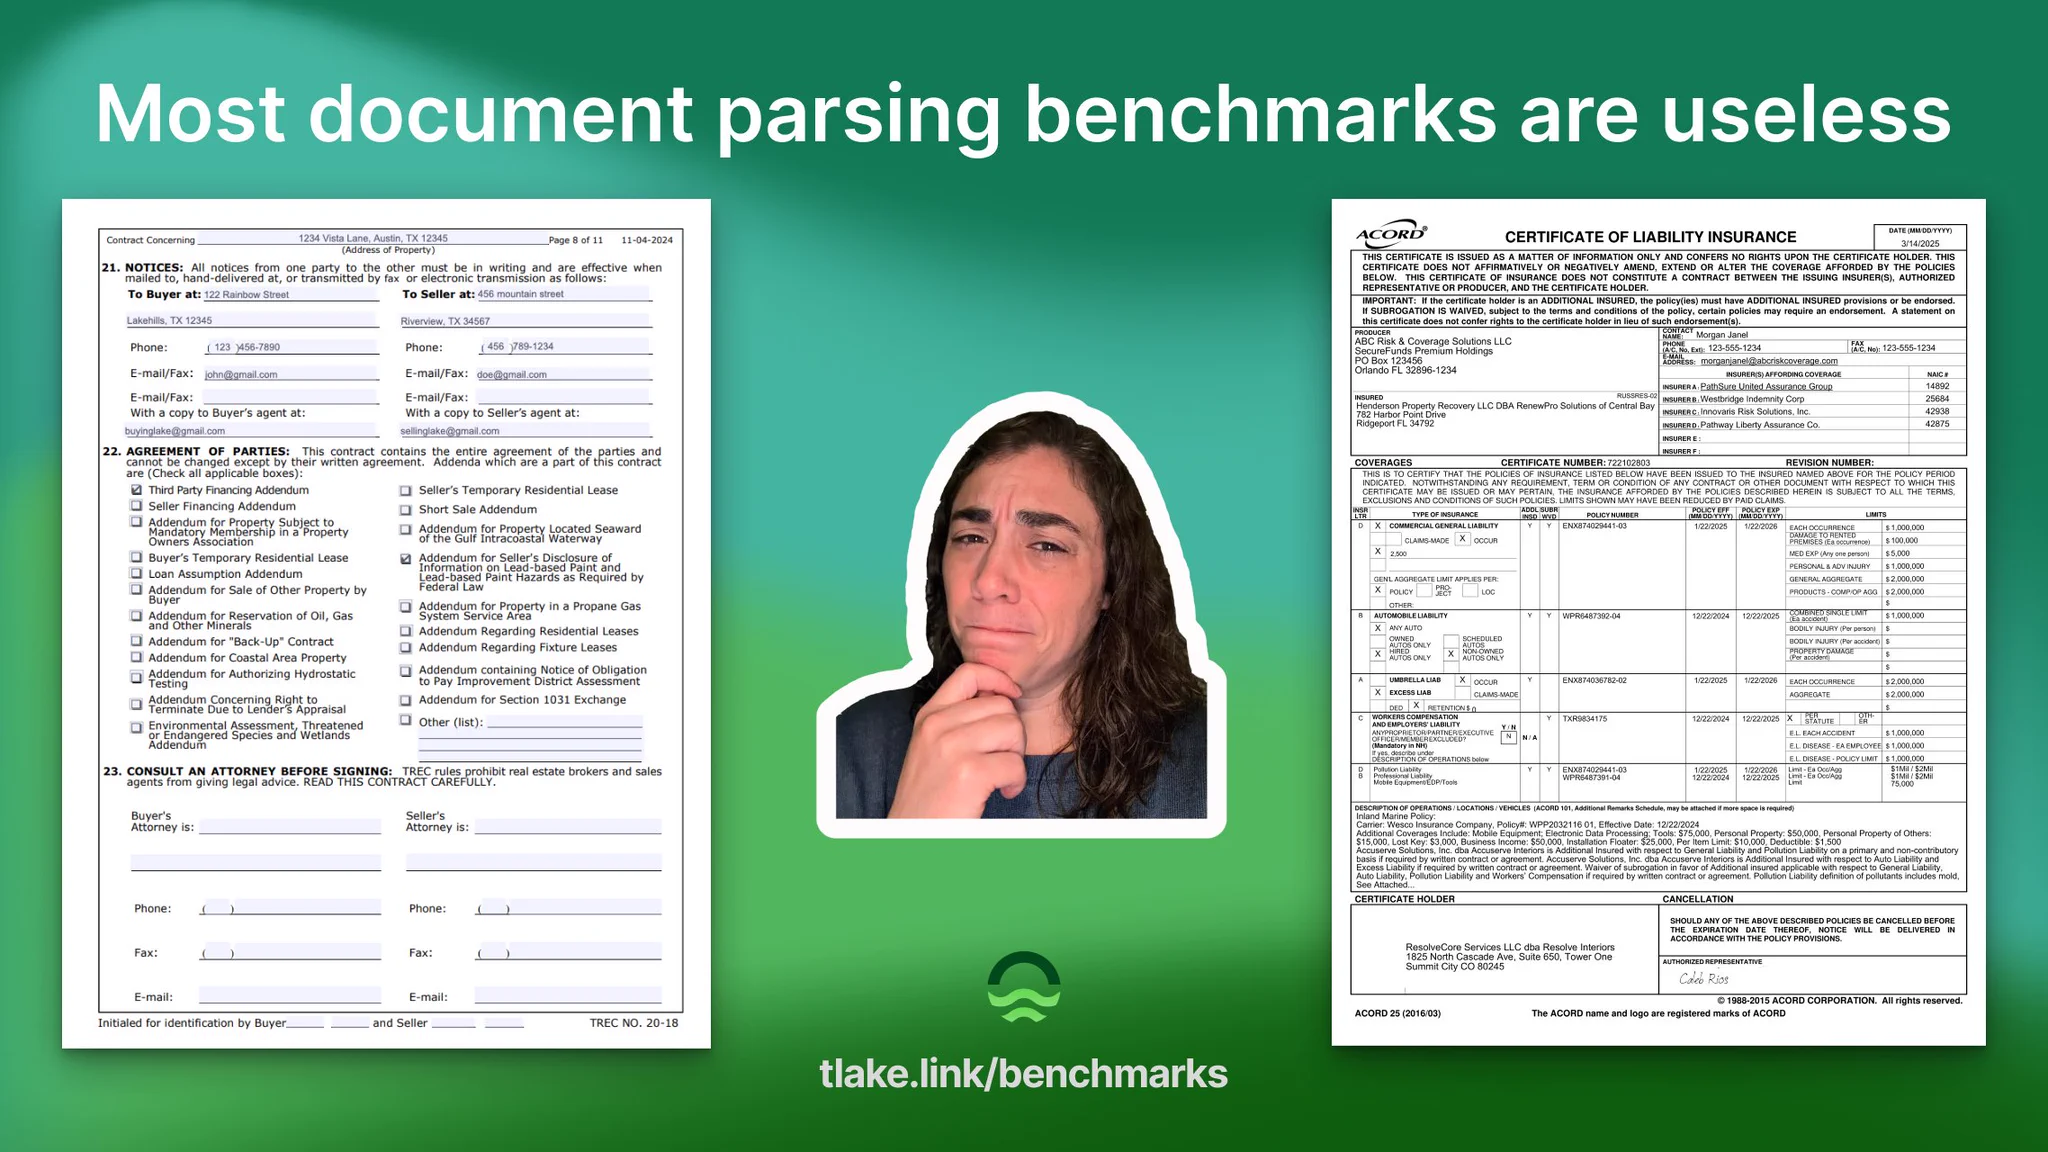
    It's time to start measuring accuracy of document parsing and data extraction with downstream systems and usability in mind, not just vanity metrics for a marketing slide
    @tensorlake
    Tensorlake
    @tensorlake
    Nov 5, 2025
    Document parsing benchmarks have been measuring the wrong thing. We tested every major parser on real enterprise documents. The results will change how you think about OCR accuracy 🧵
    Two dense document pages flank a skeptical person’s sticker-style portrait against a green gradient, link text centered below.
  • @drguthals
    Dr G
    @drguthals
    Oct 23, 2025
    Make your agents smarter with accurate and complete data Learn how to extract data from unstructured documents with @tensorlake , store them in @qdrant_engine, and then use @langchain for natural language querying. Check out our lesson 👇
    @tensorlake
    Tensorlake
    @tensorlake
    Oct 23, 2025
    Want to build scalable data lakes with Tensorlake + @qdrant_engine? In the free Qdrant Essentials Course, learn how to: - Architect vector-powered data lakes - Optimize ETL pipelines - Create knowledge graphs - Integrate @langchain agents for natural language querying Links
    Promotional banner for the Qdrant Essentials Course featuring Tensorlake. Text reads: ‘Improve collection querying with knowledge graphs.’ On the left is the Qdrant logo and course title; on the right is a smiling woman with long curly brown hair wearing a cream-colored top, set against a purple gradient grid background.