Log inSign up
Log inSign up
Phúc Lê
354 posts
Phúc Lê profile banner
@lkhphuc

Phúc Lê

@lkhphuc
lkhphuc.com
Joined December 2014
602 Following
342 Followers
RepliesRepliesRepostsRepostsMediaMedia

Log in or sign up for X

See what’s happening and join the conversation

Continue with phone
or
Log in with username or email
Terms·Privacy·Cookies·Accessibility·US TIDA·Ads Info·© 2026 X Corp.
  • @lkhphuc
    Phúc Lê
    @lkhphuc
    Apr 8
    Falcon-Perception can now be install with `pip install falcon-perception` - 1 model file - 2 variants Perception + OCR - Paged / Batch +KVCache inference engine - Torch+compile + cudagraph - Upsampler w/ async cache for high-res mask Plus: MLX batch inference support 🧵:
    @dahou_yasser
    Yasser Dahou
    @dahou_yasser
    Apr 1
    We are releasing Falcon Perception, an open-vocabulary referring expression segmentation model. Along with it, a 0.3B OCR model that is on par with 3-10x larger competitors. Current systems solve this with complex pipelines (separate encoders, late fusion, matching algorithms).
    00:00
    1
  • @lkhphuc
    Phúc Lê
    @lkhphuc
    Jul 13, 2022
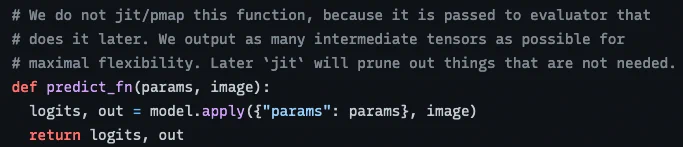
    I was browsing the BigVision codebase and wondering why the heck did they output every intermediates of a module. @giffmana @__kolesnikov__ must be working with memory at TPU-pod-level. Nope, turn out it was jax's jit, a pretty nice pattern. I'm still amazed by jit's magic.
    1
  • @lkhphuc
    Phúc Lê
    @lkhphuc
    Mar 17, 2022
    I have seen almost every combinations of my 4-word name since started going abroad. Most extreme case is my current university email address doesn’t even have my given name in it.
    This Post is from an account that no longer exists. Learn more
  • @lkhphuc
    Phúc Lê
    @lkhphuc
    Feb 5, 2022
    Wheeze. Achievement unlocked. Next objective: double my h-index.
    3
  • @lkhphuc
    Phúc Lê
    @lkhphuc
    Jan 26, 2022
    “This work shows us a lot of patterns are somehow similar in different architectures, and a model can learn how to transfer knowledge from one architecture to a different one,” said Kipf. “That’s something that could inspire some new theory for neural networks.” -@thomaskipf
    @anilananth
    Anil Ananthaswamy
    @anilananth
    Jan 25, 2022
    A graph hypernetwork predicts parameters for other #deepneuralnetworks. Imitates pre-training and cuts down on thousands of steps of stochastic gradient descent. My story for @QuantaMagazine. @BorisAKnyazev @mengyer @thomaskipf & @PetarV_93 quantamagazine.org/researchers-bu…
    1