Pinned

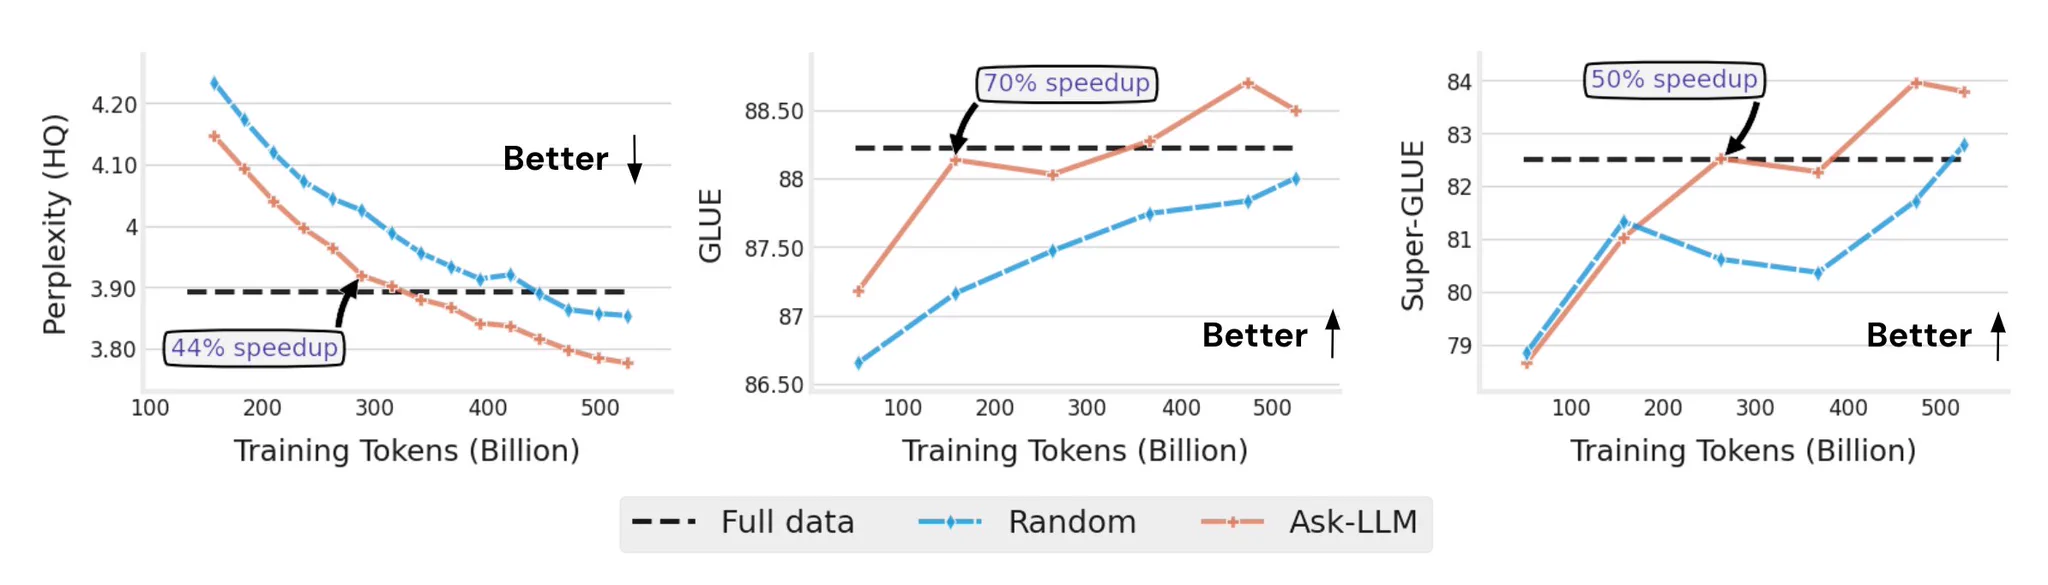
Q: Can we pre-train LLMs efficiently (and better?) via data pruning?
A: Yes!
Q: How?
A: (secret) Prompt LLMs for data quality 🤫
Check out our latest work @GoogleDeepMind - “How to Train Data-Efficient LLMs”
📖 arxiv.org/abs/2402.09668
An expensive thread 🧵(RTs appreciated!)