Log inSign up
Log inSign up
ByteShape
37 posts
ByteShape profile banner
@ByteShape

ByteShape

@ByteShape
Accelerating AI by Learning Optimal Datatypes
Canada
byteshape.com
Joined October 2024
7 Following
175 Followers
RepliesRepliesRepostsRepostsMediaMedia

Log in or sign up for X

See what’s happening and join the conversation

Continue with phone
or
Log in with username or email
Terms·Privacy·Cookies·Accessibility·US TIDA·Ads Info·© 2026 X Corp.
  • @ByteShape
    ByteShape
    @ByteShape
    Sep 18
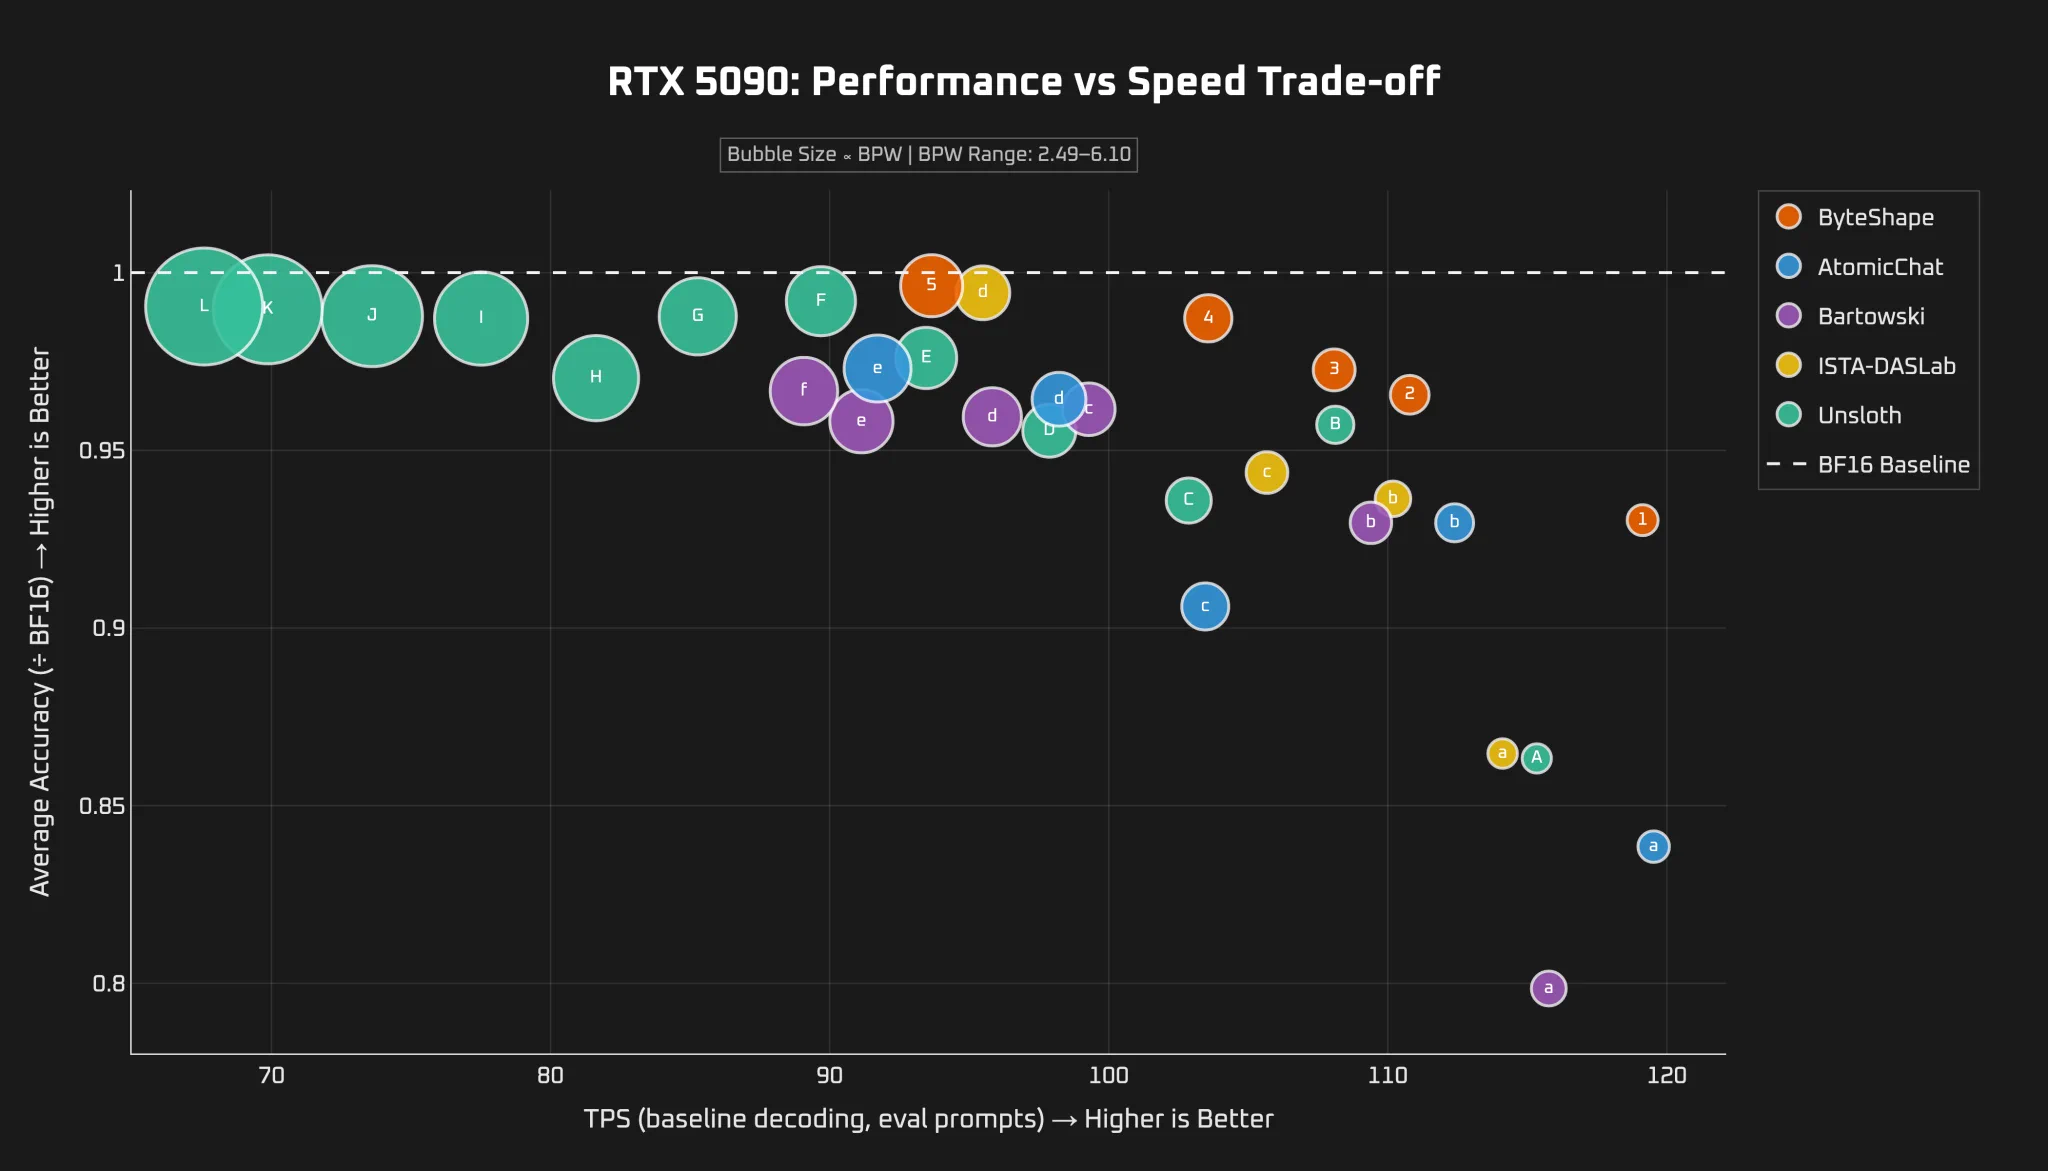
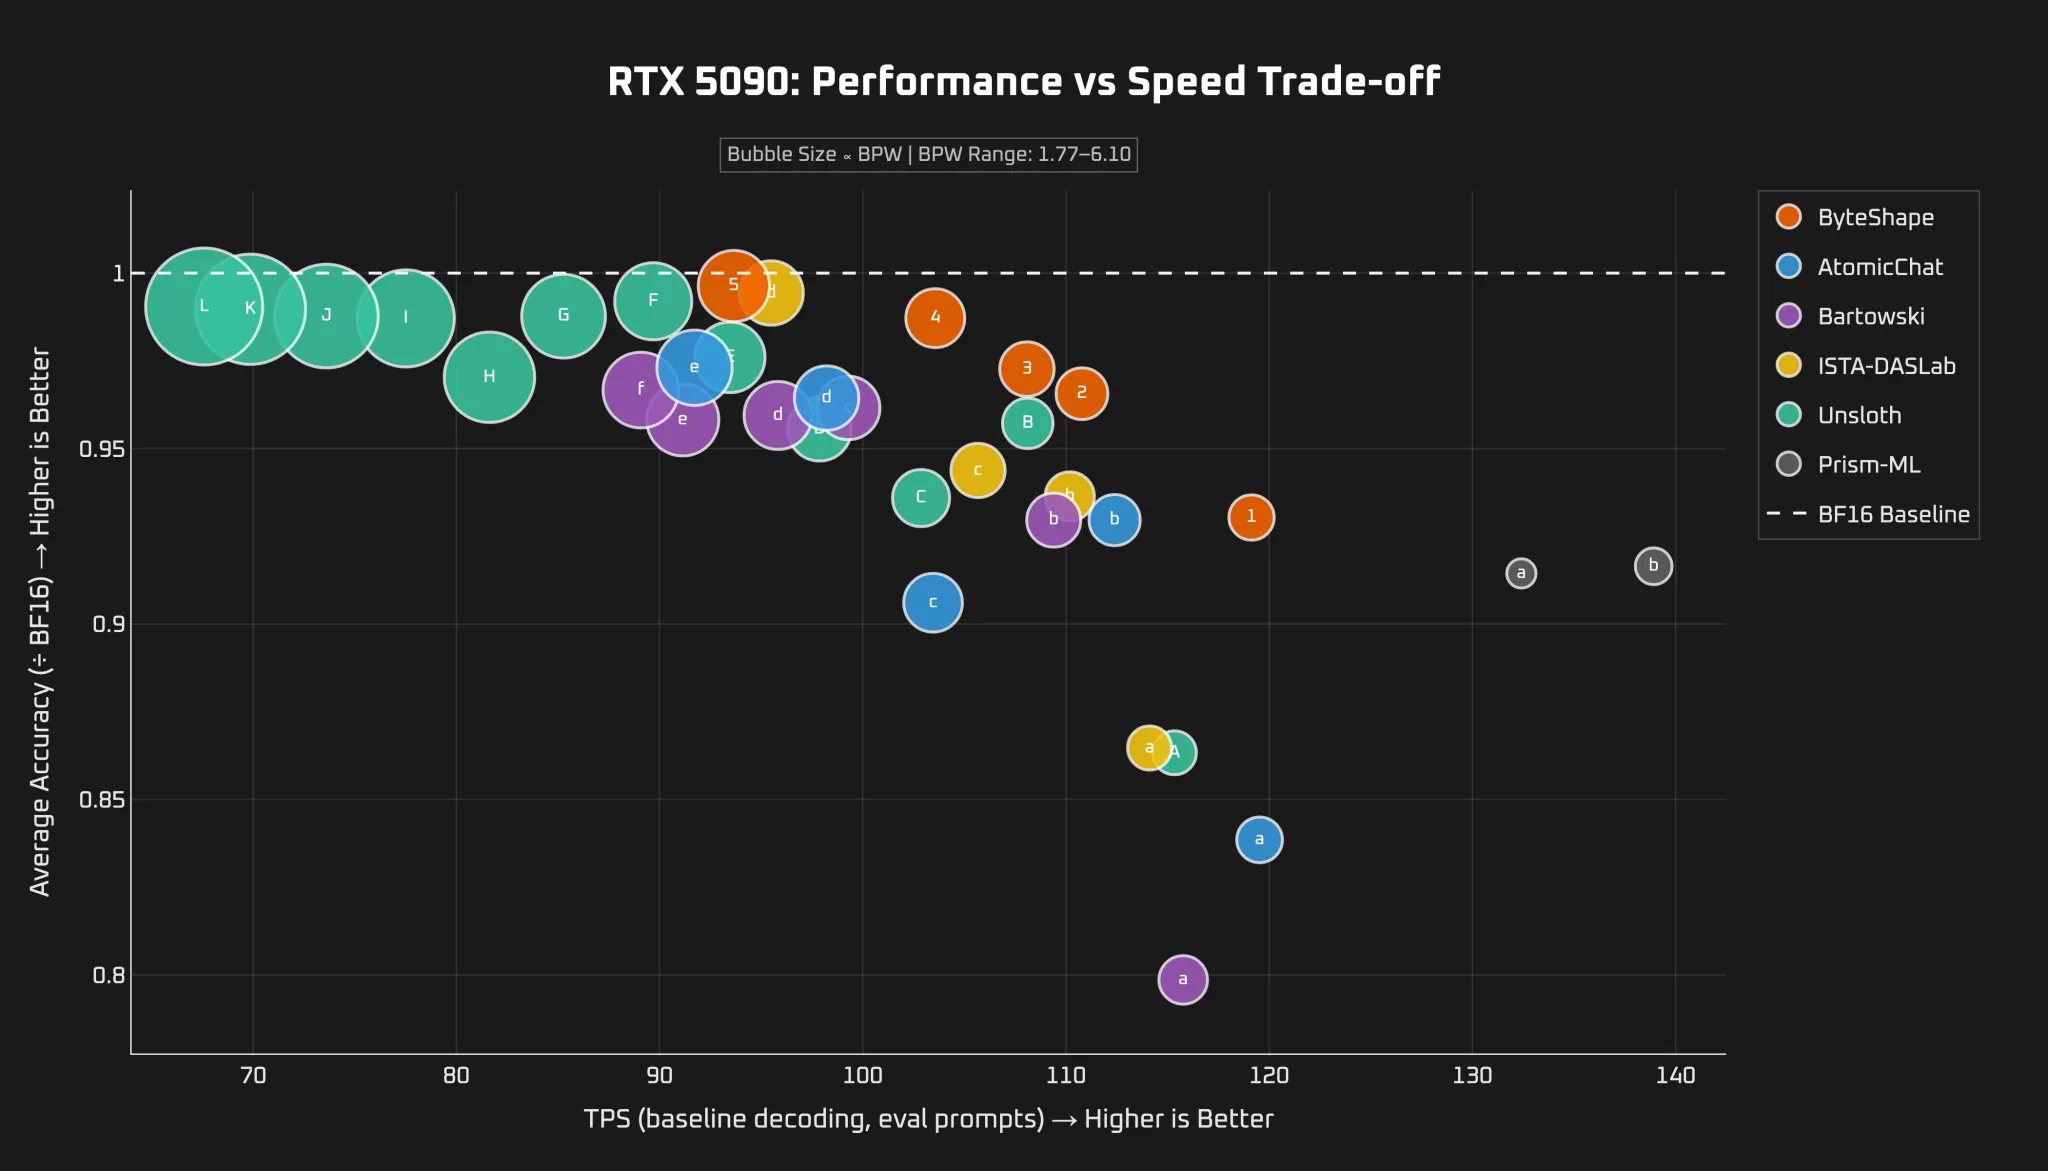
    1/3 We updated our Qwen3.8 benchmarks to include Prism-LM’s new Bonsai 2 QAT models. These are our results, not the benchmark numbers reported by Prism. We ran Bonsai 2 using Prism’s runtime, while keeping the rest of the setup consistent with our other Qwen3.8 evaluations.
    8
  • @ByteShape
    ByteShape
    @ByteShape
    Sep 15
    We released ShapeLearn-Lite days after Qwen 3.8 27B, and it already delivered some of the best quality/speed trade-offs we tested. Now full ShapeLearn is even better: 99.63% of BF16’s aggregate benchmark score at just 3.84 bpw. Models & results: byteshape.com/blogs/Qwen3.8-…
    2
  • @ByteShape
    ByteShape
    @ByteShape
    Aug 12
    We recently released two optimized image-generation models: Qwen-Image-2512 and Krea-2-Turbo. We pushed both into the ~3 bpw range while preserving their ability to generate high-quality images. Each model comes in two flavors: (1/2)
    1
  • @ByteShape
    ByteShape
    @ByteShape
    May 22
    We released Qwen 3.6 35B A3B GGUF quants in both NTP and MTP. The benchmark results made one thing clear: size, speed, and quality do not move in a straight line. GPU-5 was hard to beat. If it fits, try it first. Blog: byteshape.com/blogs/Qwen3.6-…
  • @ByteShape
    ByteShape
    @ByteShape
    Apr 13
    We recently released our Qwen 3.5 35B A3B quants. If your setup can run GPU-7, you should try it. If not, we’ve got options across all hardware. Pi → 5090. Blog: byteshape.com/blogs/Qwen3.5-…
    3