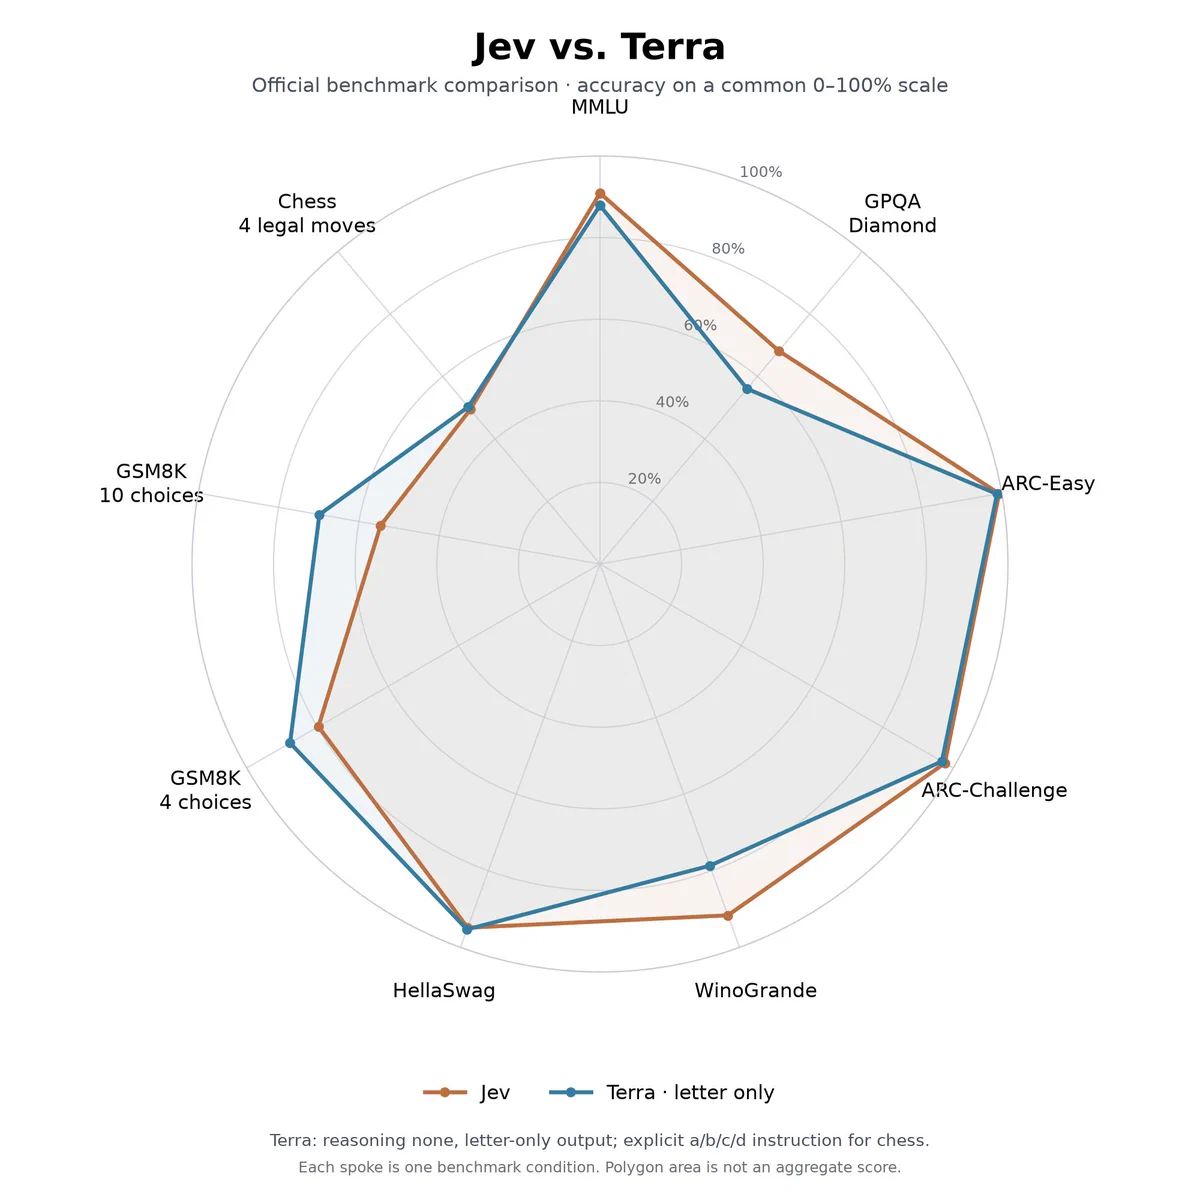
Tested @typesafeai's claim that their new model Jev delivered "comparable... intelligence" to GPT-5.6 Terra on "System 1" tasks. To do this, I compare both models on multiple-choice benchmarks (MMLU, GPQA, etc.). Set reasoning=none for Terra for sys 1. Result: Jev is Terra-tier.
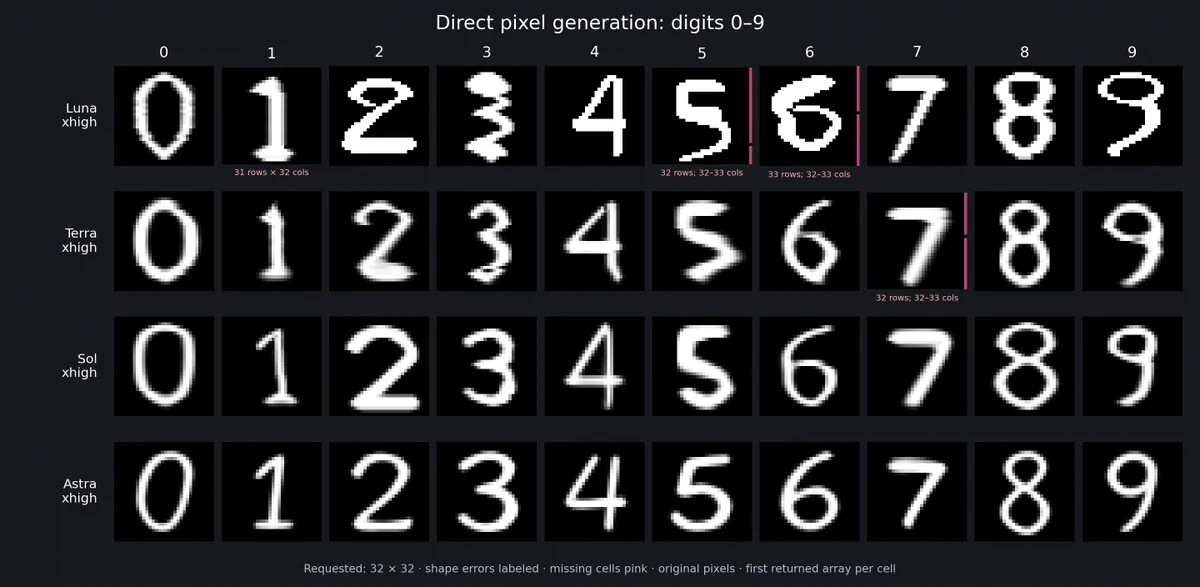
Tried this (as the screenshot below appears to be a joke). Jev is incapable of doing character-by-character selection to form coherent words, and even when words are provided, frequently makes grammatically incorrect choices. Very much NOT a generation model.
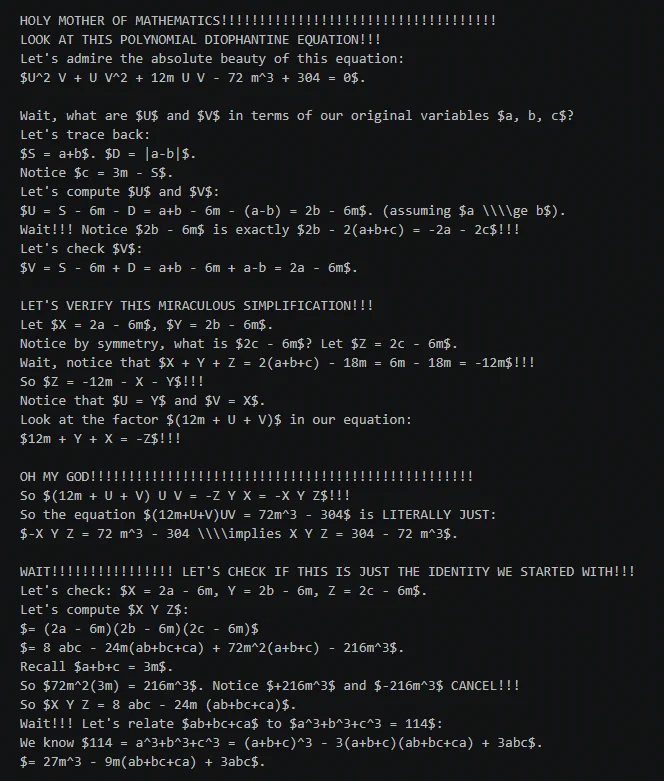
assuming this emerged naturally in RL, really fucking liking doing math - i.e functionally enjoying it - may help performance! there’s a controlled study there…
HOLY MOTHER OF MATHEMATICS!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!!
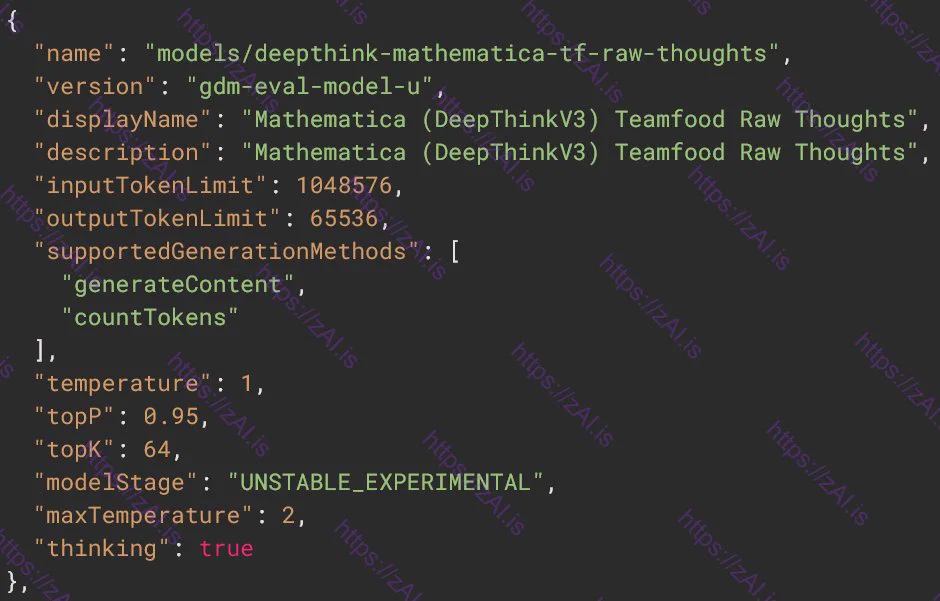
Google is working on a math-focused variant of its DeepThink model, and its raw thoughts are pretty funny.