This time we should say goodbye to PPO/GRPO for real 👋
PPO is a great algorithm in classical RL settings. However, it is fundamentally flawed in LLM regime due to the large, long-tailed vocabulary.💔
Checkout our paper for more details👇
4B parameters. ZERO distillation. 61.5% on SWE-bench Verified 🤯
Meet FrogNano 🐸: Qwen3.5-4B post-trained purely with RL on synthetic tasks from TaskPilot.
Just 5 iterations × 300 tasks.
Who said coding agents have to be huge? 🐸
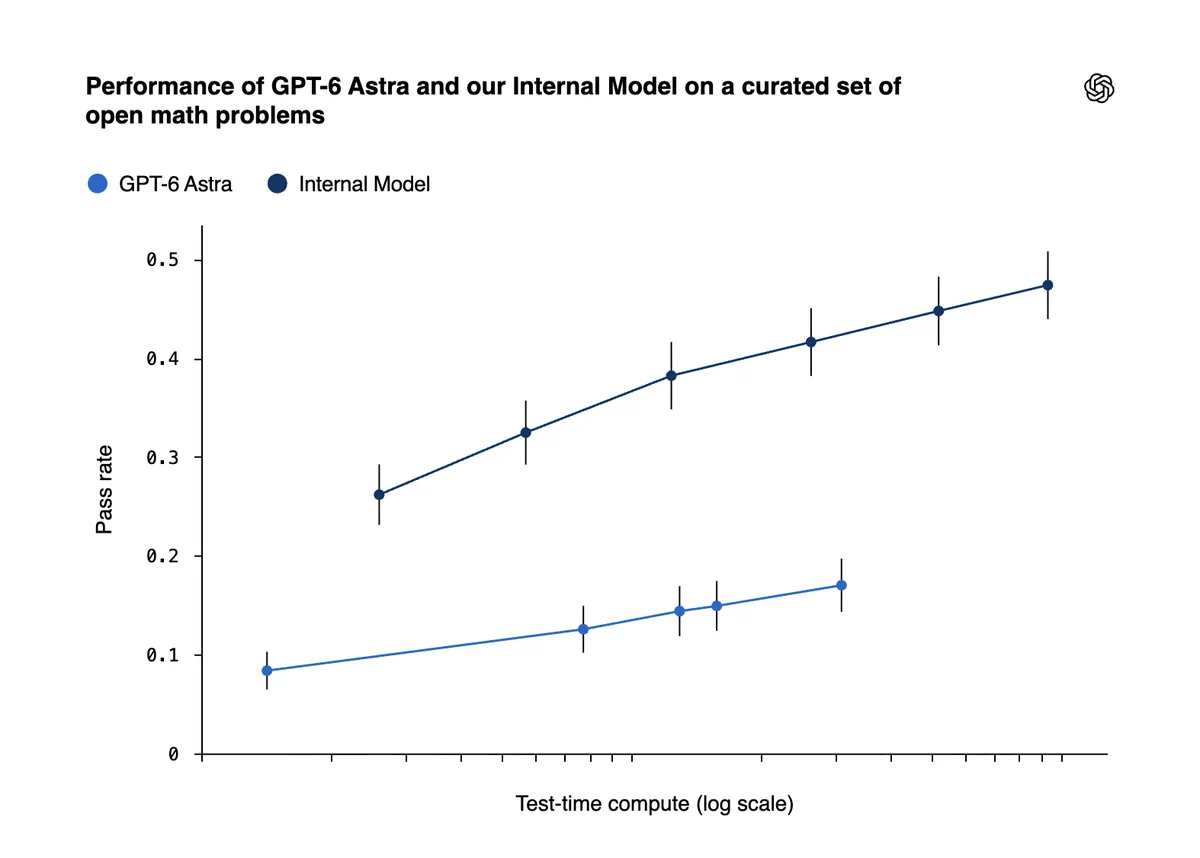
This model represents a step-function improvement on many benchmarks, and its training is ongoing.
Our internal model group arrived at the Navier–Stokes solution in 88 hours, using around 10,000 coordinating AI agents.
Throughout the effort, we maintained the strict
Can confirm this! Tested DPPO at ~300B scale RL Post-Training:
• Prevents entropy collapse
• Much faster & more stable convergence
• Great length extrapolation (e.g., trained on 256k➔ keeps scaling nicely at longer context during inference)
Awesome work! 🚀
How does one RL post-train a 397B model for long-horizon knowledge work? 👩💼
We share every step we took to bring Qwen 3.5 397B from 16.1% Pass@1 to 27.3% on APEX-Agents using DPPO, including final models weights and the full training script🚀 This is the first of many works from