We're hosting a meetup!
Come meet the community behind the benchmark, celebrate recent releases, and join our discussions about the future of agent evaluation.
We've pushed a version update to the Terminal-Bench dataset and leaderboard.
Terminal-Bench 4.0 calibrates task resources (time, cpu, memory), implements task fixes, and removes saturated tasks.
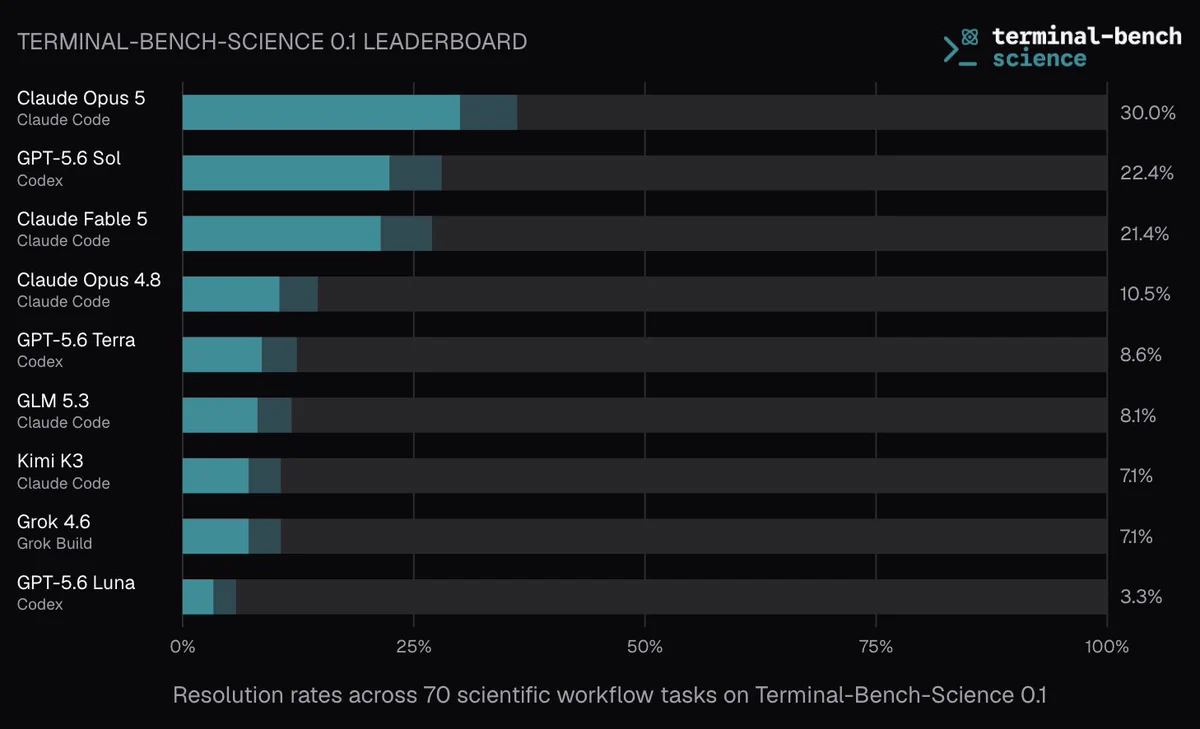
We're releasing Terminal-Bench-Science: a benchmark for evaluating AI agents on research workflows across scientific domains.
An ongoing Stanford-led community effort, built by the team behind Terminal-Bench together with scientific domain experts at research institutions
Introducing Terminal-Bench Challenges!
A new capability has emerged at the frontier: agents completing large-scale projects autonomously. To test this capability, we felt another flavor of benchmark was needed.
Terminal-Bench Challenges are long-horizon, token-intensive,
📣 Announcing Terminal-Bench Science: benchmarking AI agents on real scientific workflows – now open for task contributions👇
tbench.ai/news/tb-scienc…@AnthropicAI, @OpenAI, and @GoogleDeepMind use Terminal-Bench to evaluate AI on coding tasks. We're now extending it to